 Vineeth K Kolarath
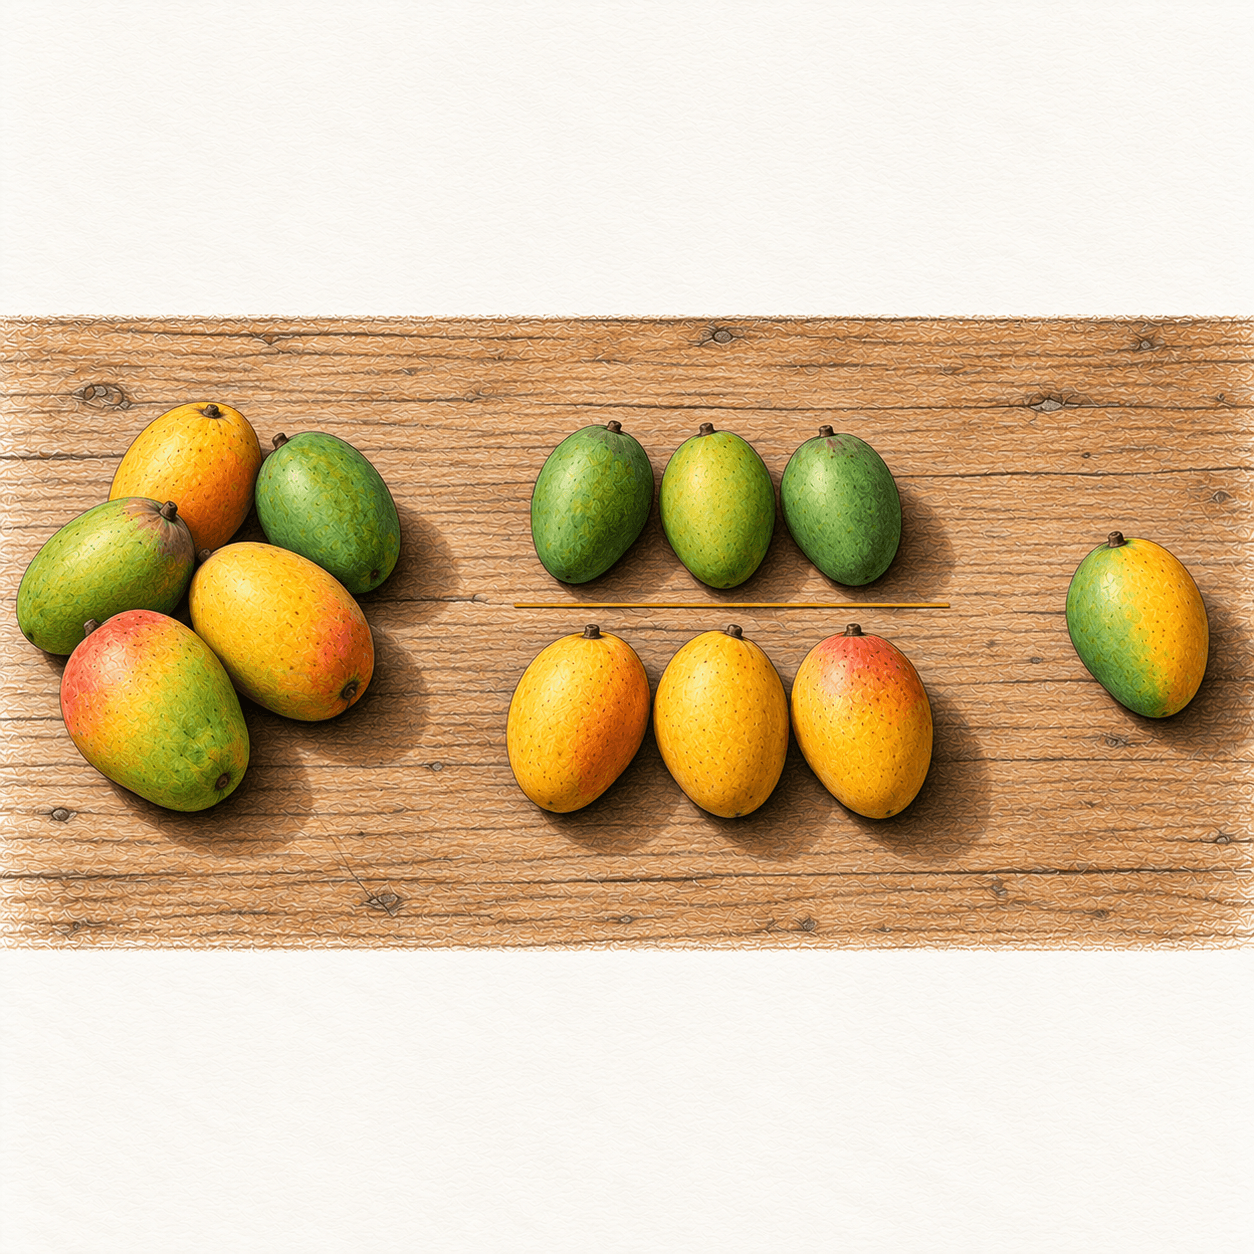
In my essay What Is a Thinking Machine?, I described a ladder with four rungs. A plain machine follows. An automatic machine reacts. A deciding machine chooses. A learning machine improves.
That last rung is the one people often find mysterious.
How does a machine learn? Usually, we do not teach it by writing a separate rule for every situation. Instead, we give it examples and a way to learn from them.
The answer is less mysterious than it sounds.
Let us take it one step at a time.
What does it mean for a machine to learn?
Computer scientists have spent decades studying this question. One widely used definition comes from Tom Mitchell's 1997 textbook, Machine Learning.
In simple terms, a computer program learns when its performance at a task improves through experience, according to some measure of how well it is doing.
There are three parts to that idea.
- A task. Something the system is supposed to do, such as sorting emails or recognising handwritten digits.
- A measure. A way to judge how well it does the task, such as how many emails it classifies correctly.
- Experience. Information it uses to improve its performance.
Notice what this definition does not require. It does not say that the machine must feel, think or understand things as a person does.
Here, learning means measurable improvement at a particular task.
That is a useful place to begin because it gives us something we can examine rather than something we have to guess about.
Start with something you already know
Let us take something familiar to many of us in India: picking a ripe mango.
How do you decide whether a mango is ready to eat?
You might look at its colour. You might press it gently or notice its smell near the stem. You may also consider the variety and how long it has been since it was picked.
You probably do not calculate a score in your head. You draw on what you have noticed over the years.
Now try to turn that experience into a few exact rules.
"If the skin is yellow, the mango is ripe."
That does not work for every variety. Some mangoes can be ready to eat while their skin is still green.
"If the mango is soft, it is ripe."
Not quite. An overripe mango can be soft, too. And how soft is soft enough?
The more you think about it, the more exceptions you find.
This does not mean the task is impossible to describe. It means that a few simple rules may not be enough.
This is one situation where learning from examples can help.
Step one: collect examples
Suppose we want to build a system that sorts mangoes into two groups: ripe and not yet ripe.
Instead of trying to write every rule ourselves, we collect examples.
We might photograph mangoes under consistent lighting. We might measure their firmness with a suitable instrument. We might also use a sensor that detects certain gases associated with ripening.
Each measurement gives us information about a mango. In machine learning, these measurements are called features.
A feature is simply a piece of information that the system can use when making a prediction.
But measurements alone are not enough for the kind of learning we are describing.
We also need to know the answer for each example. Someone with suitable knowledge examines the mangoes and labels them according to a clear definition of ripeness.
Those answers are called labels.
Now each example has two parts: the features we measured and the label we want the system to predict.
This is called supervised learning.
It sounds straightforward, but there is an important question to settle first: what exactly do we mean by "ripe"?
Are we trying to identify a mango that is ready to eat today? One that will be ready tomorrow? Or one that is suitable for selling at a particular stage of ripeness?
Those are different tasks.
The quality of the examples matters, but so does the question we ask them to answer.
Step two: find a pattern
Now we give the labelled examples to a learning system.
The people building the system have already made important choices. They have decided what task it should perform, which information to use and what kind of learning method to apply.
The method uses the examples to build a model that can make predictions about mangoes it has not seen before.
There are many ways to do this. Here are two simple approaches that help explain the idea.
Look at similar examples.
Imagine a new mango arrives. The system measures its features and compares them with examples it has already seen.
If the new mango is similar to several mangoes that were labelled ripe, the system may predict that it is ripe, too.
This is the basic idea behind a method called k-nearest neighbours, which uses the labels of nearby examples to make a prediction. The system relies on similarity rather than trying to write down a complete set of rules.
Of course, the result depends on how similarity is measured and which features are used. Two mangoes that look alike in a photograph may not be equally ripe.
Adjust a model using mistakes.
Another approach starts with a model whose predictions may be poor. During training, the system compares its predictions with the known answers and uses the differences to adjust the model.
This process is repeated according to the learning method being used. Over time, the model may become better at predicting the labels.
The details can be mathematical and complicated. But the broad idea is simple: use examples to adjust a model so that its predictions improve.
These two approaches work differently. Not every learning system compares each individual guess with a label and then adjusts itself in the same way.
But both illustrate the central idea: examples can help a system make predictions without a person having to write a separate rule for every possible case.
This stage is called training.
The system does not work in isolation. People choose the task, the learning method and the information it receives. The model is built from those choices and the examples.
Step three: test it on mangoes it has never seen
Here is a trap that catches beginners.
After training the system, it is tempting to test it on the same mangoes it learned from.
It may perform very well. But that does not tell us enough about how it will handle new mangoes.
Think of a student who memorises the answers to last year's question paper. They may score very well if given the same paper again. Give them different questions, and the result may be very different.
A machine can run into a similar problem.
It may fit its training examples so closely that it learns details that do not generalise to new cases. This is called overfitting.
A model that overfits can perform impressively on familiar examples and poorly on unfamiliar ones.
To check this, we set aside some examples before training begins. The system does not use these examples to learn its model.
After training, we evaluate the model on this separate test set. Ideally, these examples represent the kinds of cases the system will encounter in practice.
During development, a separate validation set can help people compare models and adjust their settings. The test set is best kept for a final, independent evaluation.
The test set should also remain separate from decisions made while developing the model. If we repeatedly use its results to change the model, we are no longer getting an independent test.
A good test gives us better evidence about how the system may perform on new mangoes. It cannot guarantee that every real-world situation will be covered.
That is why testing matters.
Step four: see how it behaves in the real world
Suppose our system performs well on the test examples. Is the job finished?
Not necessarily.
Imagine that most of our examples came from one mango variety, photographed in one market during one season.
Now the system is used somewhere else, with different varieties, lighting conditions or ways of measuring the fruit.
Its predictions may become less reliable.
The system has not necessarily broken. It may simply be facing conditions that were poorly represented in the examples it learned from or the tests it passed.
This is one reason learning systems need to be monitored after they are put into use.
People should check whether the predictions remain useful and whether mistakes are appearing in particular situations. If the system's performance declines, the team may need to investigate the cause, collect better examples, change the model or retrain it.
Retraining is not always the answer. Sometimes the problem lies in the sensors, the way the task was defined or the conditions in which the system is being used.
Learning is not a guarantee that a system will keep working well forever.
Where learning goes wrong
There is no single reason that learning systems fail. But several common problems are worth understanding.
Too few or too narrow a set of examples.
A small collection of mangoes may not represent the varieties, sizes, stages of ripeness and conditions the system will encounter. The system may learn a pattern that works for those examples but not for others.
More examples can help, but quantity alone is not enough. The examples need to be relevant to the task.
Important cases are missing.
Suppose our collection contains ripe and unripe mangoes but no examples of spoiled fruit. The system may struggle to recognise spoilage because it was not trained to distinguish that condition.
This is a simplified example, but the problem matters beyond fruit.
In the 2018 Gender Shades study, researchers Joy Buolamwini and Timnit Gebru evaluated three commercial gender-classification systems. They found substantial differences in error rates across the demographic groups they tested, with darker-skinned women experiencing the highest error rates in their evaluation.
The study examined particular systems and datasets at that time. It did not establish that missing examples are the only cause of every performance gap. But it demonstrated why systems should be tested across the groups and conditions that matter, rather than judged by one overall score.
Wrong or inconsistent labels.
Imagine that the person labelling the mangoes disagrees with another expert about which ones are ripe. Or some labels are simply entered incorrectly.
The system may learn from those mistakes. If the definition of the task is unclear, collecting more examples will not necessarily solve the problem.
The features do not tell us enough.
Suppose the system measures only the size of a mango. Size alone is unlikely to tell us reliably whether it is ripe. Large mangoes can be unripe, and small ones can be ready to eat.
A system needs information that is useful for the task. More complicated learning methods cannot always compensate for poor measurements.
The system learns the wrong clue.
Imagine that, in our collection, every ripe mango was photographed on a white plate and every unripe mango on a brown tray.
The system might learn to distinguish the plates rather than the mangoes.
Its results could look good if the test examples have the same arrangement. In a shop where mangoes are displayed differently, the predictions could fail.
This is an example of a model relying on a misleading shortcut.
The lesson is not that every failure comes from bad examples. Failures can also come from the learning method, the way the system is built, the measurements, or the conditions in which it is used.
We need to examine the whole process.
Two kinds of predictions
So far, our system has been asked to choose between categories: ripe or not ripe.
This is called classification.
But sometimes we want a number instead.
How many days might remain before a mango is ready to eat? How much water might a field need tomorrow? How many packets of rice might a shop sell next week?
Predicting a number is often called regression in machine learning.
The tasks differ, but the broad process can be similar. We collect relevant examples, train a model, evaluate its predictions and check how well it performs in practice.
A prediction is not a promise. If a model estimates that a mango will ripen in two days, the actual time may be different. The estimate is useful only to the extent that it is reliable for the conditions in which we use it.
What has the machine actually learned?
It is worth pausing here.
Our mango system has found a pattern connecting measurements to labels. It may be very useful at predicting ripeness.
But we should not assume that making a good prediction means the system understands mangoes in the same way a person does.
It does not need to know that mangoes are eaten at home, sold by the roadside or shared with friends. Those facts may matter to people, but they are not necessarily part of the task the model was trained to perform.
The system's capabilities depend on what it was built to do and what it learned from its data.
It may also make a prediction when the situation is unfamiliar. Some systems can estimate uncertainty or flag certain unusual inputs, but those safeguards are imperfect. A model may still produce a confident-looking answer when it is wrong.
A 2017 study by Chuan Guo and colleagues found that the neural networks they examined often produced confidence estimates that did not match their actual accuracy. This is one reason a model's reported confidence should not automatically be treated as proof that its answer is correct.
So when a learning system gives us an answer, we should ask two questions.
How often is it right in the situations that matter?
And how would we know when it is wrong?
Why this matters to you
You may never build a learning system yourself. But you are likely to encounter them in everyday life.
They help sort messages, recommend videos, estimate travel times and support decisions in areas such as banking and healthcare.
You do not need to know the mathematics behind every system to ask sensible questions about it.
- What task was it built to perform?
- What examples did it learn from?
- Who labelled those examples, and how were disagreements handled?
- Which people or situations might be missing?
- Was it tested on examples kept separate from training?
- Has anyone checked how it performs in real use?
- Who is responsible when its prediction is wrong?
These questions will not tell you everything about a system. But they help you look beyond a polished demonstration or a confident answer.
They also remind us that a learning system is not automatically fair, reliable or useful just because it uses machine learning.
Those qualities have to be examined.
Try this
Here is a small exercise you can do with paper and a pencil.
Choose something you can sort by looking. Ripe and unripe bananas. Fresh and wilted leaves. Perhaps different kinds of handwriting.
Start by deciding what you want to distinguish. Try to make the categories clear enough that you can label examples consistently.
Then choose three features you can observe, such as colour, size or texture.
Collect ten examples. For each one, write down the three features and your label.
Now look at your table.
Can you see a pattern? Does one feature seem more useful than the others? Are there examples that do not fit the pattern?
Next, find two new examples that you did not include in your original table. Before checking their labels, use your pattern to predict where they belong.
With only ten examples, you should not expect a dependable learning system. The point is to experience the process and notice its limits.
You have collected examples, assigned labels, looked for a pattern and tried it on something new.
That is the beginning of the idea.
In my first essay, Bring a Rough Idea, I asked you to bring a rough idea. This time, bring your table of ten examples.
Do not worry if your pattern is imperfect. Look at where it works, where it fails and what you might need to change.
That is how learning begins: not with a machine that knows everything, but with examples, careful questions and the willingness to check what happens next.